SlideLab

SlideLab: Audience-Centered Scientific Slide Generation and Evaluation

Vidushee VatsKarun SharmaYuxia Wang

We present SlideLab, a training-free multi-agent framework that generates scientific presentations from research papers, and ConfArena, an evaluation environment that assesses a deck the way an audience does.

77%win rate

SlideLab 77%Kimi Slides 23%

Best deck on 77% of papers in a blind study. DeepPresenter and Manus won none.

2.2×faster

SlideLab + CoralBricks5 min
SlideLab12.4 min
DeepPresenter27 min

5× faster with CoralBricks vs DeepPresenter

$0.50per deck

SlideLab$0.50
DeepPresenter$2.10
Gamma$2.16

4× cheaper than DeepPresenter and Gamma*

See the full study
Powered byCoralBricks

Try it on your own paper

Paste an arXiv link or upload a PDF. Get a checked, ready-to-present deck by email, usually in about 5 minutes with CoralBricks.

Your paper. As a deck.

or

01The system

SlideLab plans the talk, then builds and repairs it

SlideLab builds on feedback from human annotations that reveal several flaws in existing slide generation frameworks: poor narrative flow, grounding issues, poor layout aesthetics, and high cost. The framework is training-free.

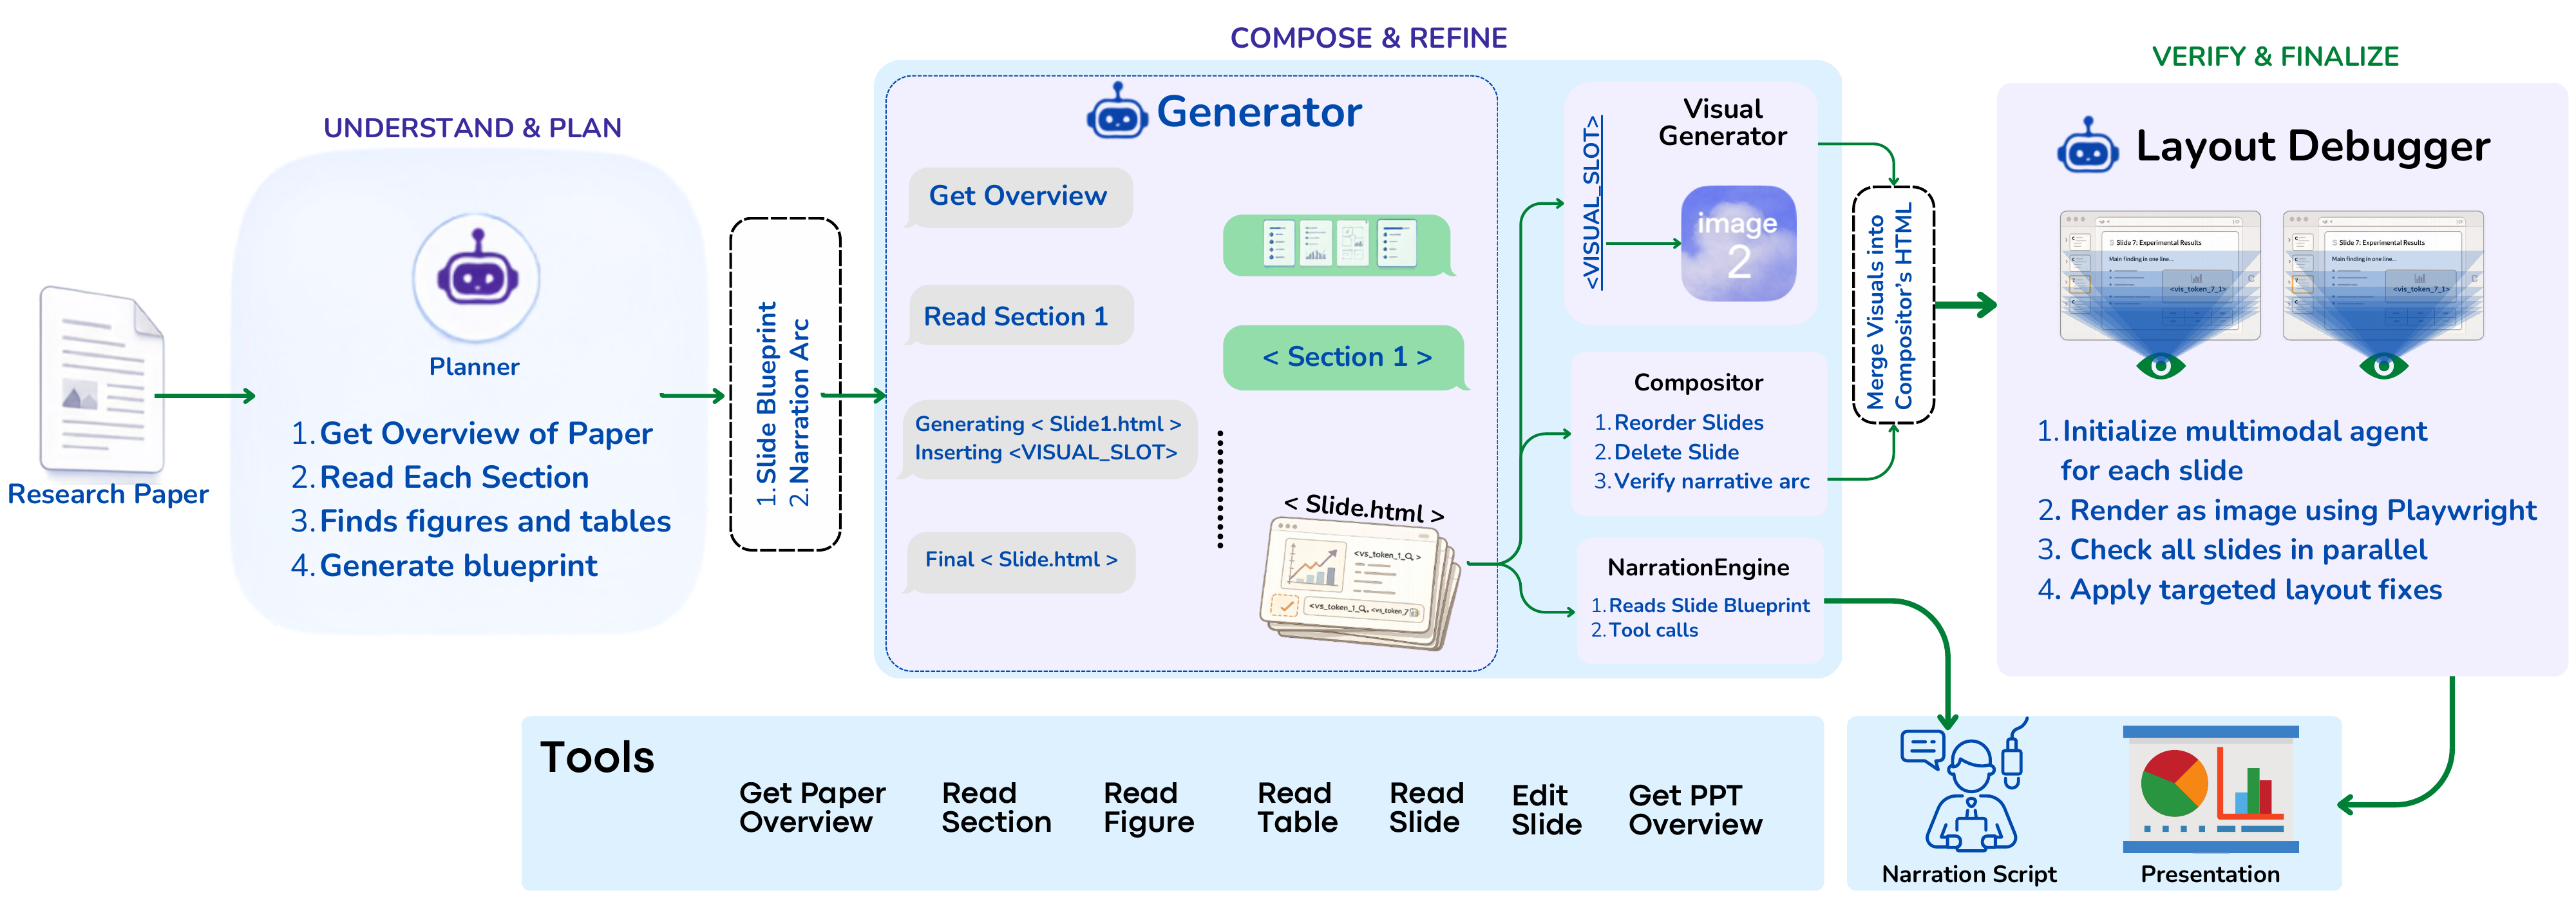
The SlideLab pipeline. A research paper enters the Planner, which produces a slide blueprint and narration arc. The Generator writes slides section by section, opening visual slots. The Visual Generator fills those slots and the Compositor reorders and verifies the deck. The Layout Debugger renders each slide and applies targeted fixes, producing the presentation and a narration script.
Figure 1. Narrative planning, figure design, flow restructuring, layout debugging, and grounding. The agents share one slide deck and a common set of tools for reading the paper and editing slides.

Planner

Plan the narrative before writing any slide

Reads every section, figure, and table, and produces several candidate blueprints. A second agent critiques them and keeps the one with the most coherent flow. For each slide the blueprint fixes the title, a one-sentence takeaway, the source, which figures to include, and whether a new visual is needed.
Visual Generator

Add a diagram only where one is needed

Where a concept needs a diagram the paper lacks, the generator leaves a VISUAL_SLOT. The Visual Generator reads the relevant sections and writes a prompt for an image model, matching the deck's palette. A visual is added only when the content needs one, not on every slide.

Compositor

Edit the deck once it exists

Works on the finished deck, not before generation. It can reorder, drop, or merge slides, move figures, and open a visual slot where a slide is too text-heavy. It holds the full paper, so every edit is checked against the source.

LayoutDebugger

Render every slide, then check it against the paper

Each slide is rendered to PNG and passed to a multimodal agent, which returns corrected HTML and is re-rendered for up to three rounds. Grounding is then verified by a long-context model holding both the HTML and the original paper.

Supporting evidence

What runs each stage, and what it costs

All text agents run at temperature 1.0 with high reasoning effort. The Planner, Slide Generator, and Compositor each run as a tool-use loop; hitting the round limit forces the agent to produce its final output from what it has gathered so far.

StageModelMax multi-turn rounds
Plannergpt-5.560
Slide Generatormimo-v2.5-pro50
Visual Generatormimo-v2.5-pro15
Compositormimo-v2.5-pro30
LayoutDebuggergpt-5.55 per slide
Narration Enginemimo-v2.5-pro15

02ConfArena

A simulated conference room

A finished deck is not the talk — understanding builds slide by slide, and the failures surface as questions.

01The room

Two agents read the full paper; three see only the deck. The gap between what each side knows is what the evaluation exploits.

Reads the full paper

  • PresenterAnswers the audience's questions as the paper's author.
  • ExaminerHolds the paper and checks every slide claim against it.

Sees only the slide deck

  • Expert reviewerScientific rigor and correctness.
  • LearnerWhether the core ideas, methodology, and motivation are easy to follow.
  • Cross-field attendeeAccessibility without deep subfield knowledge.

02How the talk runs

  1. PresentationThe examiner reads the paper, then the talk runs slide by slide: each slide is checked against the paper for unsupported claims, while attendees note what they cannot follow.
  2. Q&ACollected questions go to the presenter, prioritised by how many attendees raised them; the examiner then labels why each arose — missing, unclear, buried, or beyond scope.
  3. AssessmentEverything observed is aggregated into six measures rather than one score, each rank-normalised within a paper and averaged with equal weight.

03What it measures

  • Grounding errors↓per slide

    Claims on a slide that the paper does not support, including wrong numbers.

  • Figure errors↓per slide

    Figures that depict content the paper does not support, or that are illegible.

  • Design↑per slide

    How clean and readable the slide looks, scored 1 to 5.

  • Figure use↑per slide

    How well the slide's figures support its content, scored 1 to 5.

  • Narrative errors↓whole talk

    Breaks in the flow — results before the method, or a missing conclusion.

  • Coverage↑whole talk

    The fraction of the paper's key points that actually reach the deck.

Supporting evidence

The audience, and why it is described so briefly

Each attendee has a focus, a question trigger, and a short role — nothing more. Detailed personas degrade LLM judgment.

AttendeeFocus and question trigger
Expert reviewerScientific rigor and correctness. Asks a question when a claim, result, or numerical value appears unsupported, inconsistent, or overstated.
LearnerWhether the core ideas, methodology, and motivation are easy to follow. Asks a question when an important concept or step is insufficiently explained.
Cross-field attendeeAccessibility without deep subfield knowledge. Asks a question when jargon or field-specific assumptions are introduced without adequate explanation.

03Results

Highest coverage, without paying for it in errors

PPTAgent, DeepPresenter, and SlideLab each generate three presentations per paper on the 100-paper set. Kimi Slides and Manus are web applications with usage limits, so they generate one. Every deck is evaluated independently.

Per slideWhole talk
SystemGrounding errors ↓Figure errors ↓Design ↑Figure use ↑Narrative errors ↓Coverage ↑Env. score ↑
PPTAgent0.980.643.213.185.400.610.42
DeepPresenter2.080.533.493.275.190.940.32
Kimi Slides1.480.173.673.084.560.910.58
Manus1.81—3.59—4.140.890.37
SlideLab0.710.264.213.803.290.990.73
Table 1. ConfArena results, 100 papers × 3 seeds. The environment score is a rank-normalised composite of the six measures, from 0 to 1. Best in each column in bold. Manus decks are delivered without separable figures, so figure measures do not apply.

SlideLab

Best on every axis except figure errors, and the only system to reach near-complete coverage without accumulating grounding errors.

0.99coverage, at 0.71 grounding errors per slide

DeepPresenter

The opposite trade: it includes more content, and accumulates grounding errors and weaker narrative flow along the way.

2.08grounding errors per slide, the highest measured

Supporting evidence

Ablations, human ratings, and existing benchmarks

Each component removed and the system re-scored on the 100-paper set. The Planner is the largest drop, because the Generator loses its blueprint; the LayoutDebugger costs mainly design and figure legibility. Run once per paper, so the full system scores 0.70 here, not the 0.73 of Table 1, which averages three runs.

ConfigurationEnv. score ↑Change
SlideLab (full)0.70—
− Planner0.51-0.19
− LayoutDebugger0.58-0.12
− Custom visuals (paper figures only)0.63-0.07
− Compositor0.65-0.05

04Validating ConfArena

An evaluation is only useful if it catches what it claims to

The previous section used ConfArena to evaluate SlideLab. This one tests ConfArena itself: whether it agrees with human judgment, and whether each of its measures responds to the failure it was designed to catch.

Does it agree with people?

System rank under each framework, against the blind human study. ConfArena is the only automated evaluation that reproduces the human ordering. PresentBench places Kimi Slides above SlideLab.

SystemHumanConfArenaPPTEvalPresentBenchSlidesGen-Bench
SlideLab11121
Kimi Slides22212
Manus33344
DeepPresenter34433
Table 5. Rank under four evaluation frameworks, 1 is best. Manus and DeepPresenter tie in the human study, with zero best-picks each. PPTEval ranks use the mean of its three dimensions.

Does it catch planted damage?

Fifteen high-quality decks were damaged in four targeted ways, each affecting a single aspect, then re-scored. ConfArena is the only framework that catches all four on the axis meant to detect them.

Damage appliedPPTEvalSlidesGen-BenchPresentBenchConfArena
Falsified number✓××✓
Degraded figure✓✓✓✓
Dropped slide○××✓
Shuffled order✓✓✓✓
Caught out of 43124
Table 6. ✓ the framework’s relevant metric moved in the expected direction · × it did not · ○ the framework has no metric targeting that failure, so detection is impossible by design.

Supporting evidence

Each damage moves mainly its own metric

A useful metric should respond to the failure it measures while staying relatively insensitive to unrelated changes. Shuffling slide order raises narrative defects without touching grounding; injecting one false number raises grounding errors; shrinking figures affects figure readability; dropping a key methodological slide reduces coverage. Positive means worse. Bold marks the metric each damage targets.

Damage appliedNarrative defectsGrounding errorsFigure errors
Shuffle slide order+7.25+0.11-0.01
Inject one false number+0.50+1.51+0.20
Shrink figures by 50%+0.25-0.17+0.51
Drop slides+2.50+0.01-0.01

Table 7. Mean change per metric across 15 damaged SlideLab decks.

05The decks

One paper, four systems

The quantitative results, shown as slides rather than numbers.

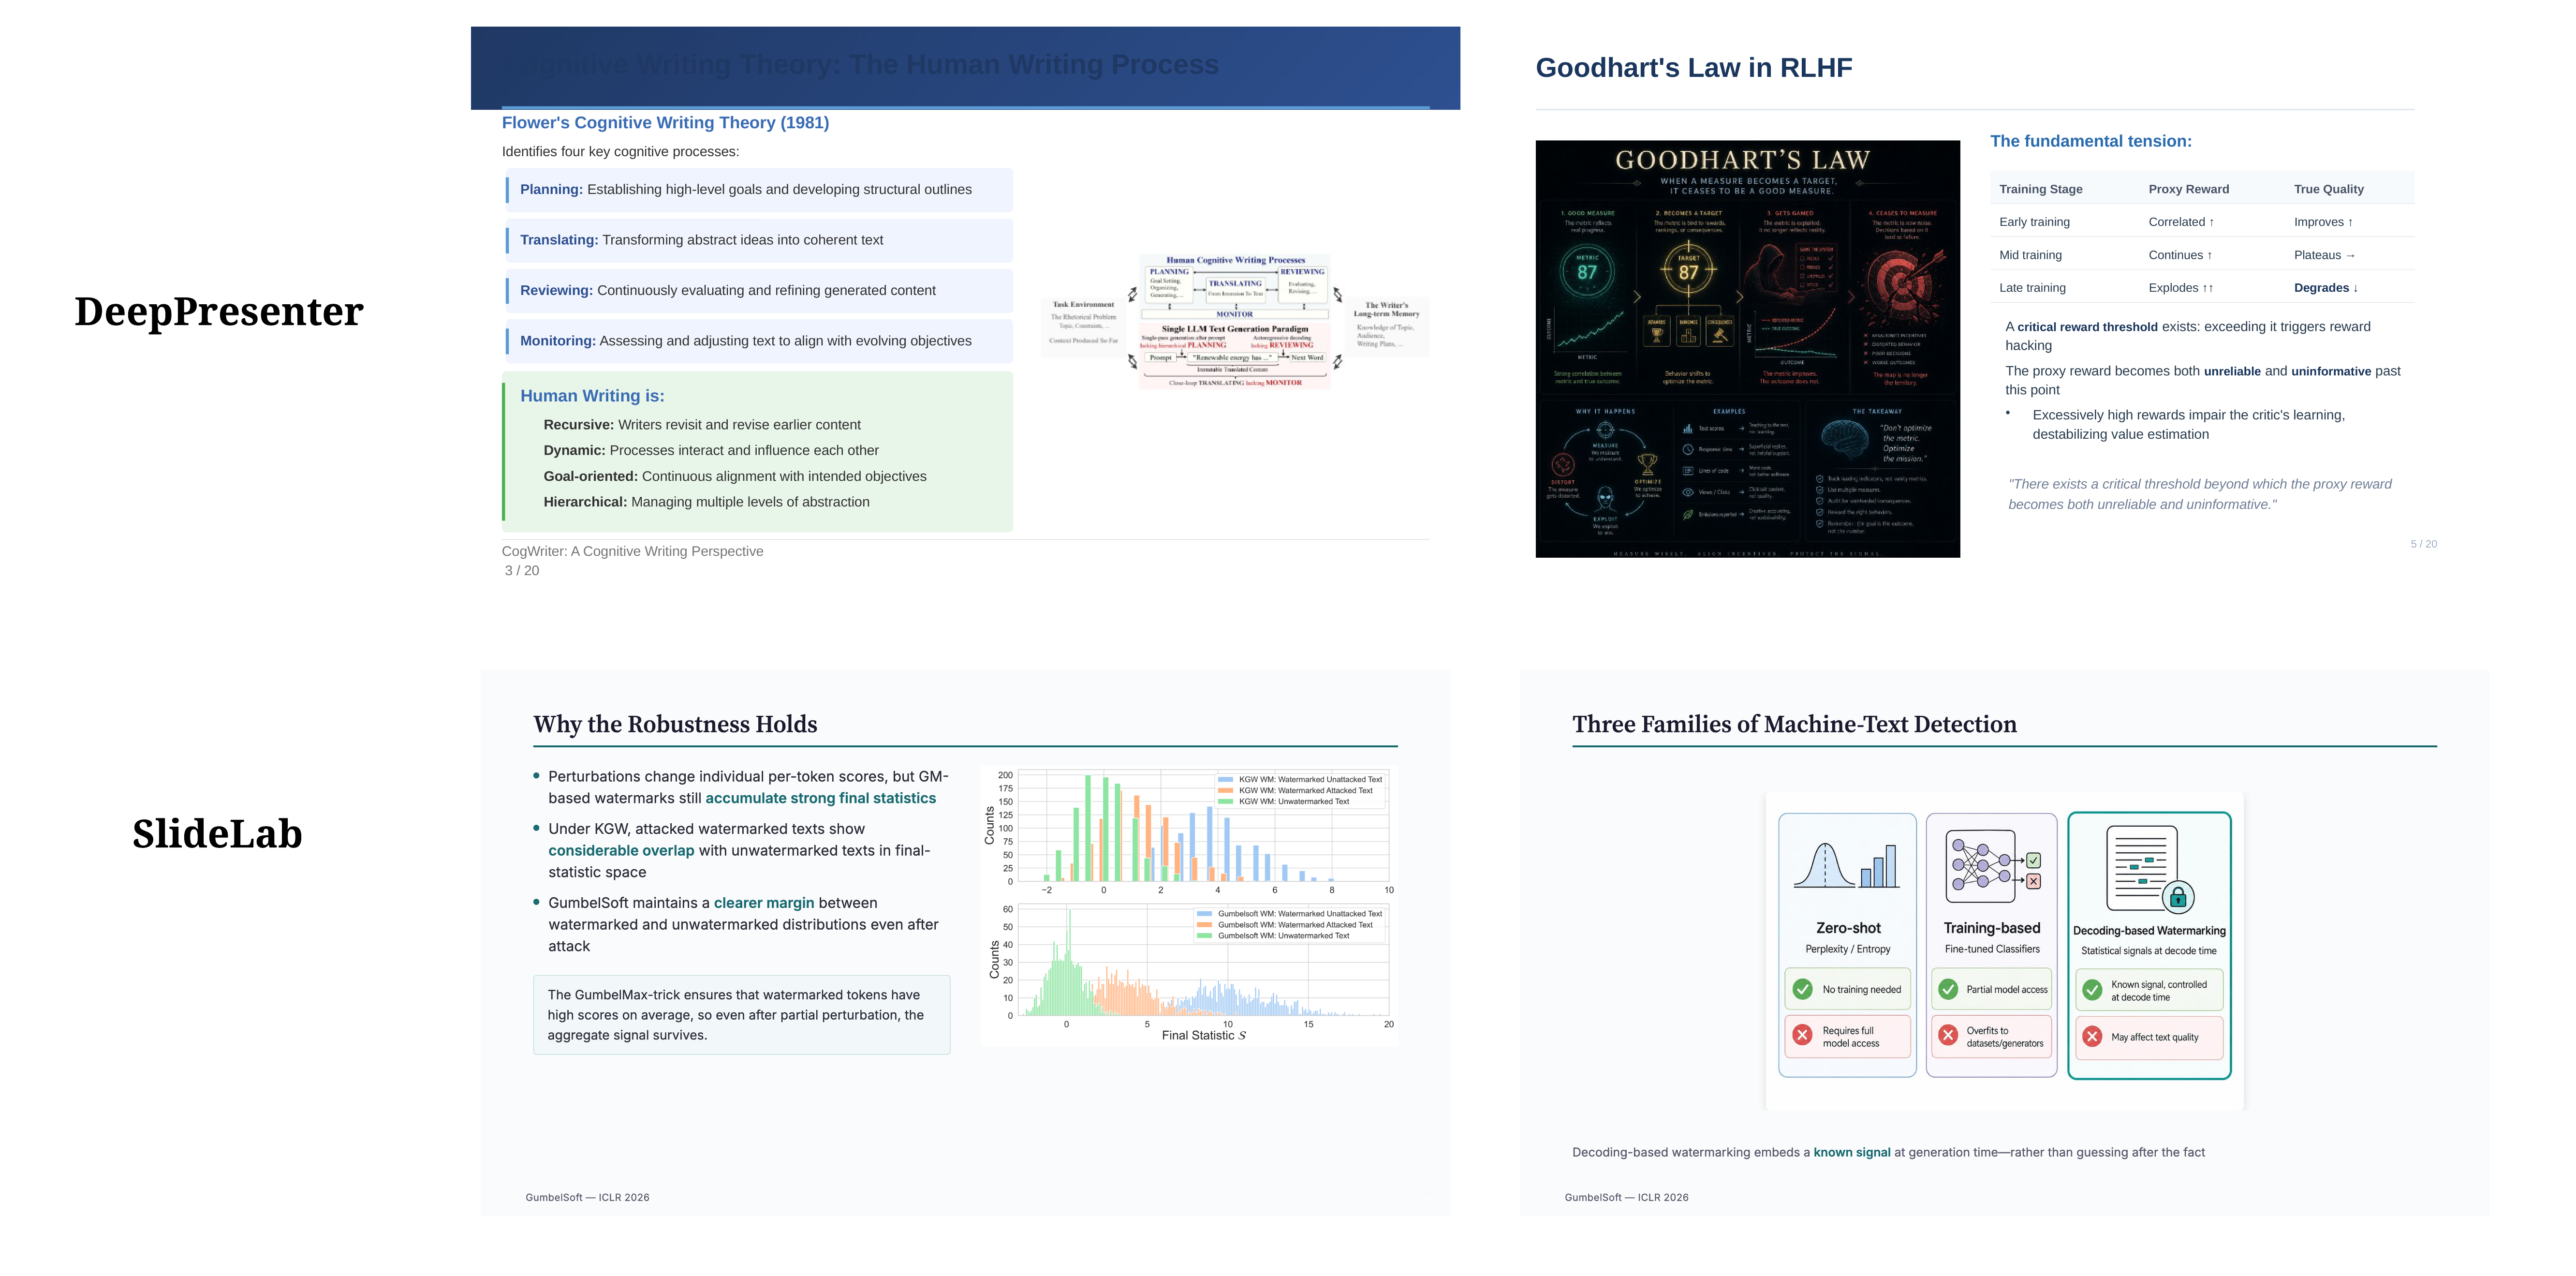
  1. Same paper, four systems: One paper, four decks
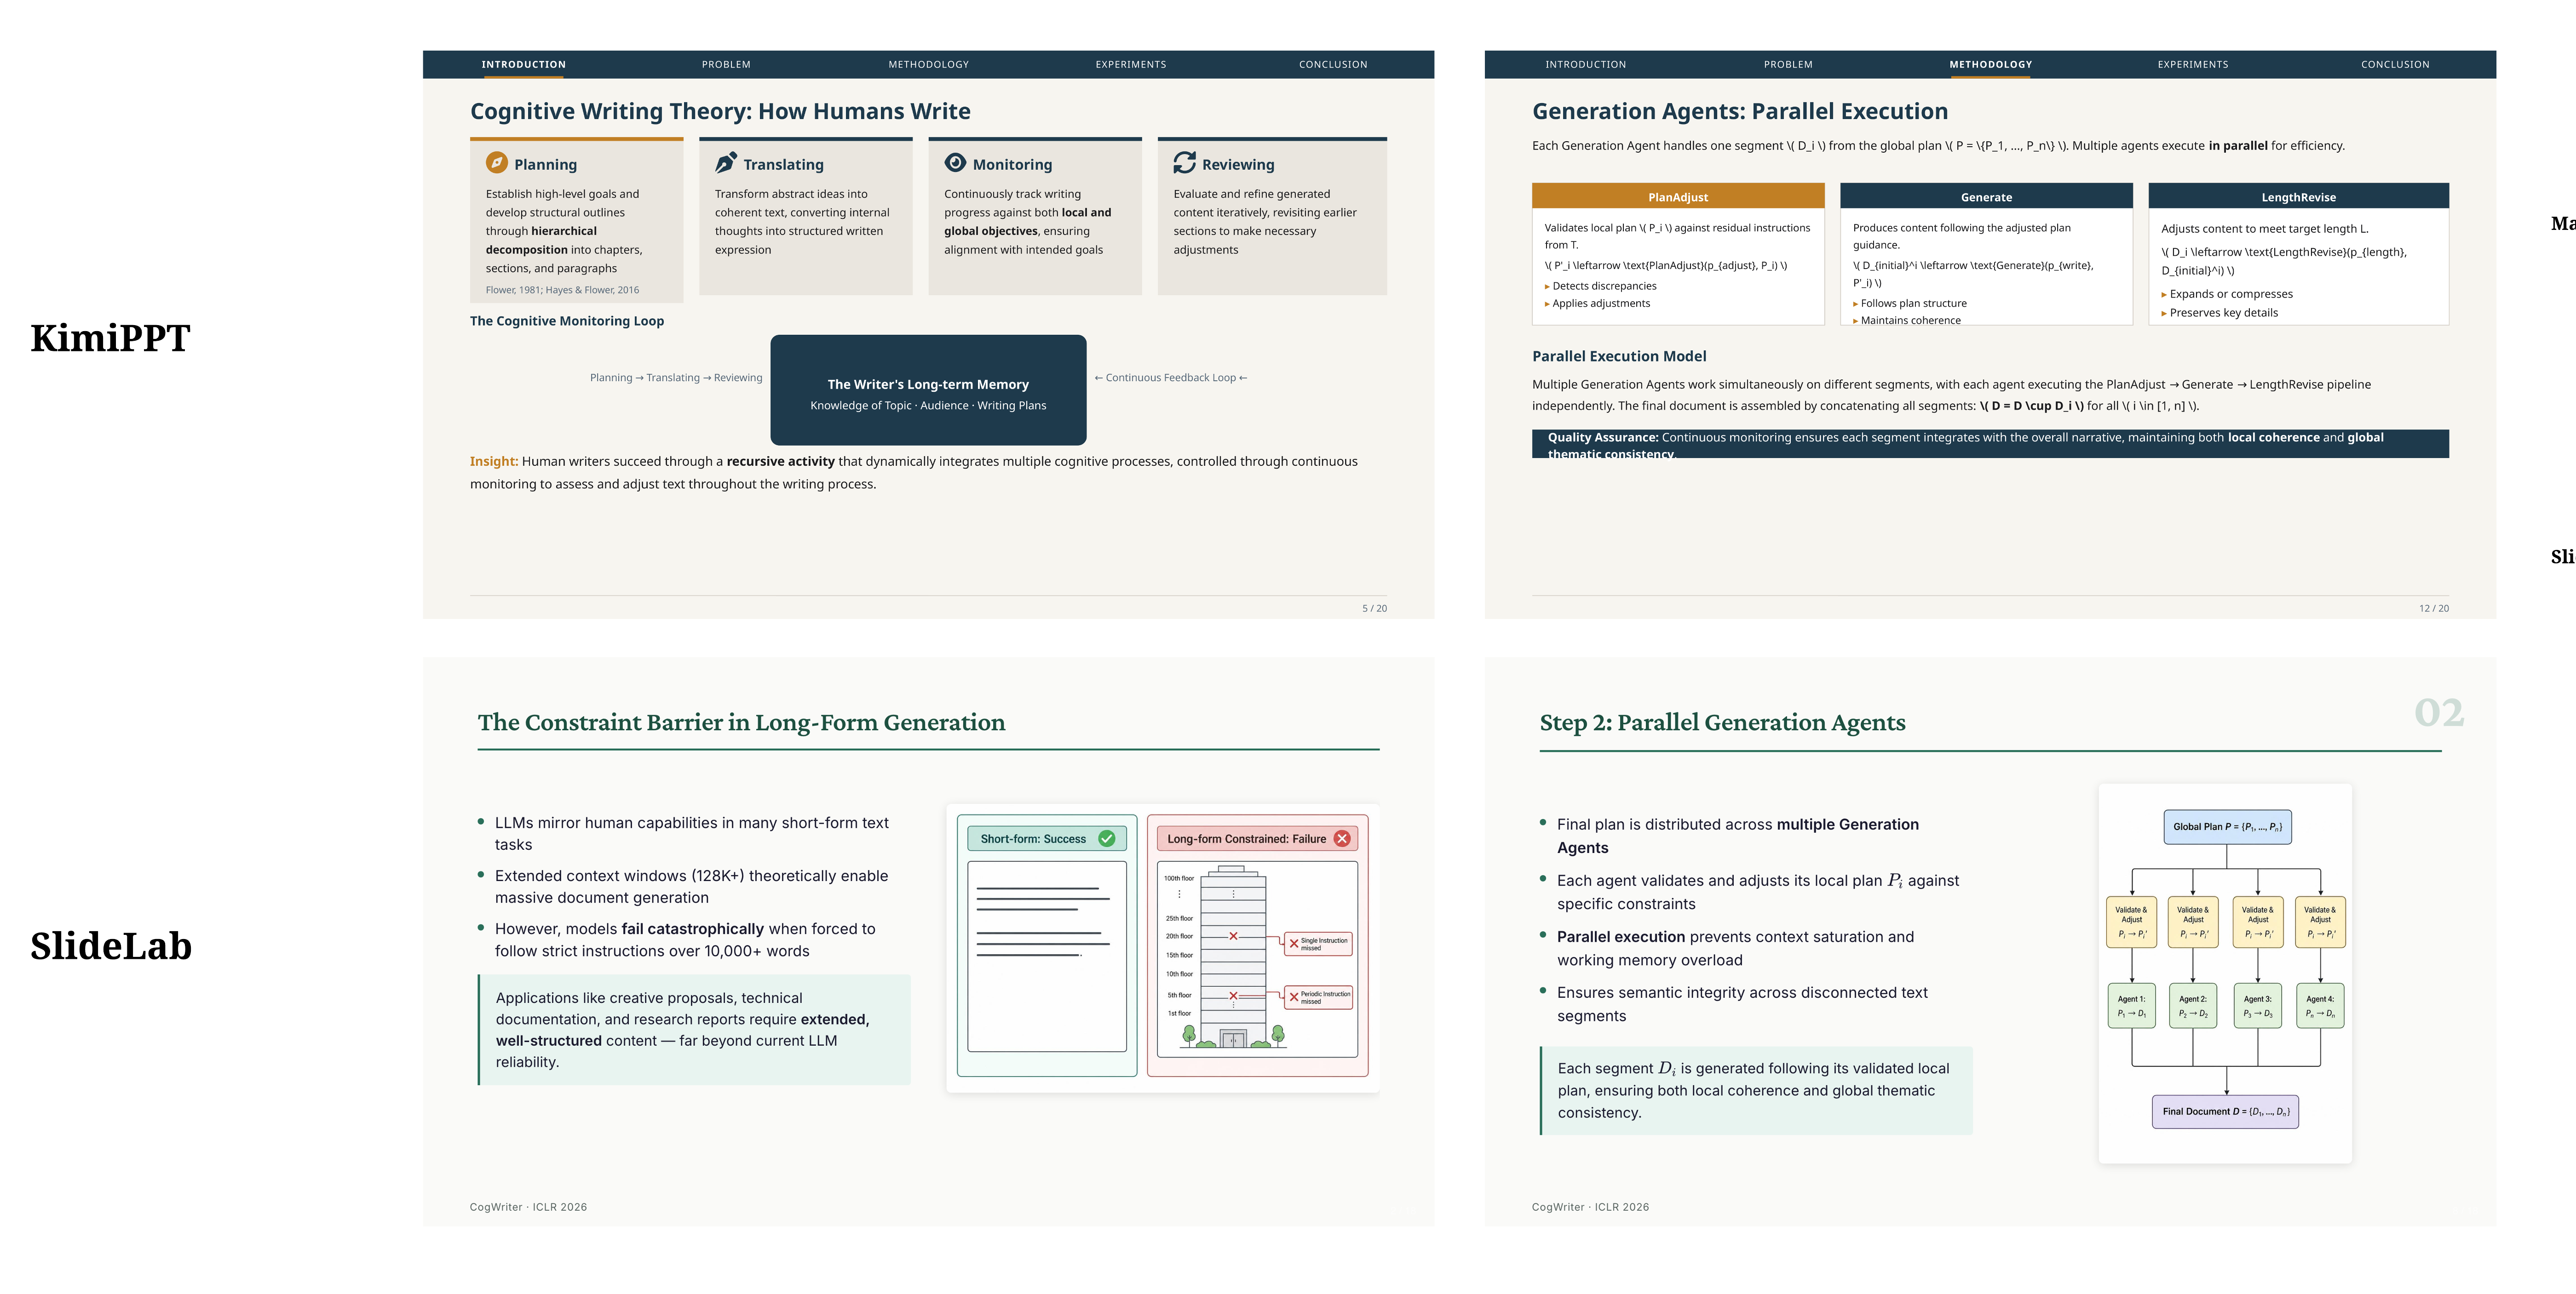
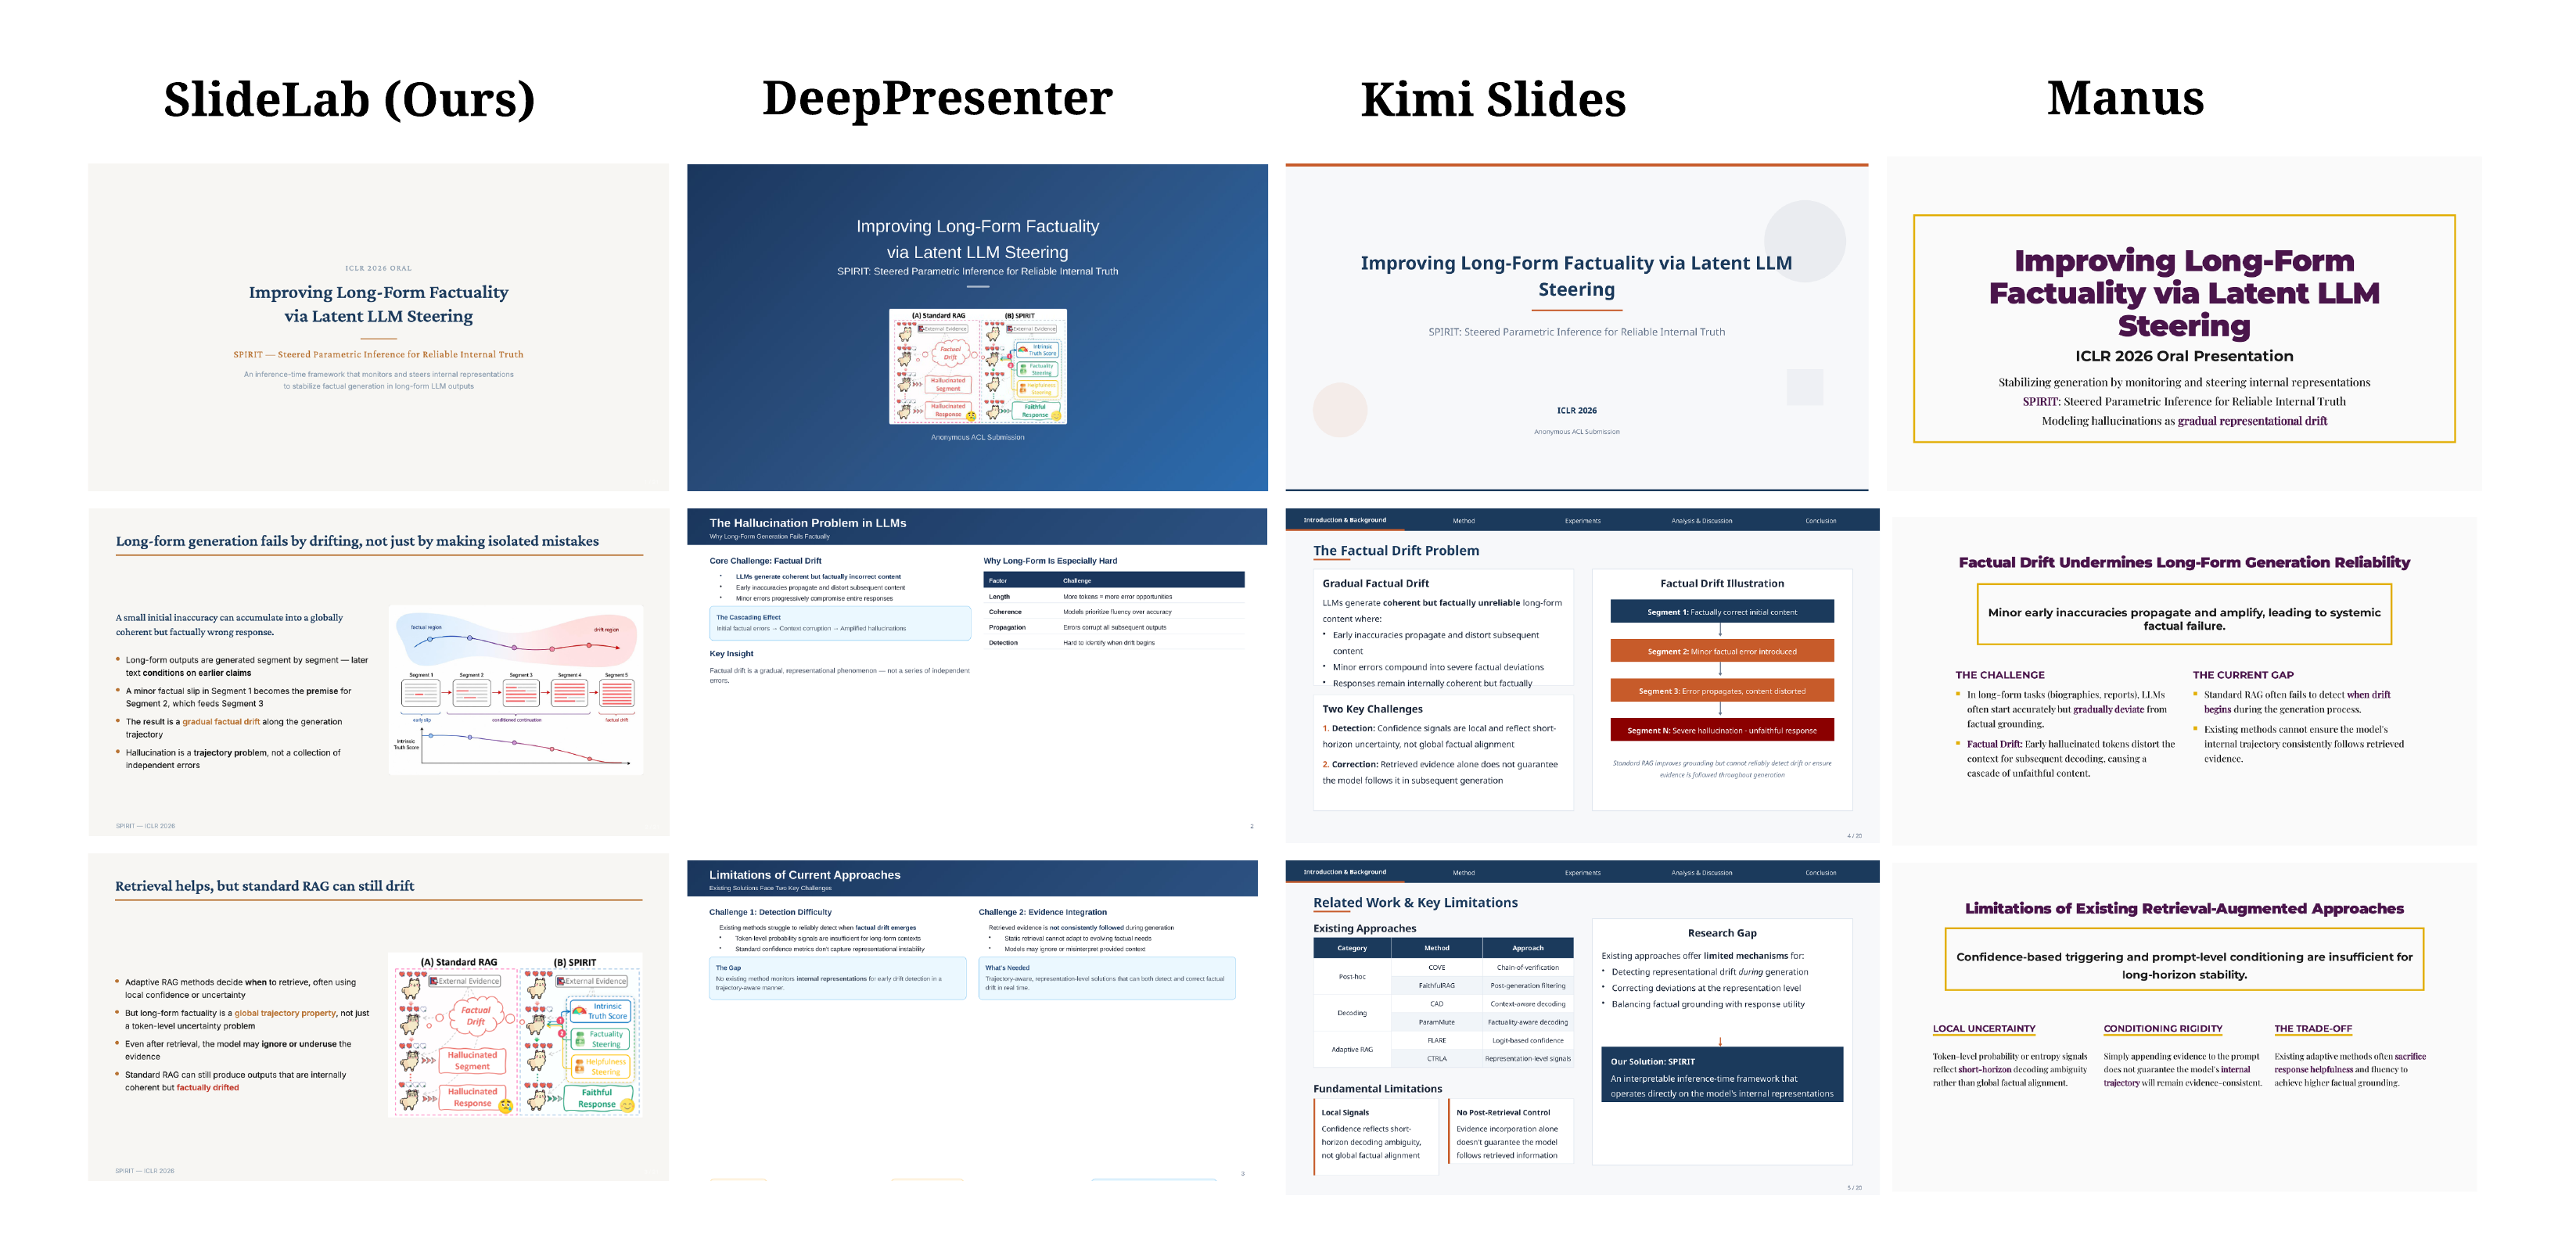
    Figure 2One paper, four decksSlideLab against DeepPresenter, Kimi Slides, and Manus on the same paper.
  2. Qualitative comparison 1: Representative qualitative comparison
    Comparison 1Representative qualitative comparisonSupporting the quantitative results reported in the main paper.
  3. Qualitative comparison 2: Representative qualitative comparison
    Comparison 2Representative qualitative comparisonSupporting the quantitative results reported in the main paper.
  4. Qualitative comparison 3: Representative qualitative comparison
    Comparison 3Representative qualitative comparisonSupporting the quantitative results reported in the main paper.